Showing posts with label odds ratio. Show all posts

10.10.08

Calculation of adjusted odds ratio using Proc logistic
Prepared by Resmi Sukumar
Adjusted odds ratios are the odds of a dichotomous event adjusted for or controlling for other possible variables in the model. For example in a model where the response variable is the presence or absence of a disease, an odds ratio for a binomial exposure variable is an adjusted odds ratio for the levels of all other risk factor included in the model.

Adjusted odds ratio and corresponding 95% confidence interval is obtained by performing logistic regression analysis, this technique is implemented in the SAS® System using PROC LOGISTIC.

Logistic regression analysis provides adjusted odds ratio if adjustors are used as additional predictors, otherwise it provides unadjusted odds ratio.

The general syntax of PROC LOGISTIC is:

PROC LOGISTIC DATA=dsn ;
MODEL depvar = indepvar(s)/options;
RUN;

Example:
Suppose we are interested in conducting a case control study to evaluate the relation among cases and controls between different genotypes. The different gene statuses are ‘abnormal’ and ‘normal’ where normal is considered as referent group. For this purpose we generate a dataset as follows

/*Random data generation*/

data genestat;
do i=1 to 50;
gene=round(1 + (3-1)*uniform(10));
age =round(1+(3-1)*uniform(15));
ethnic=round(1+(3-1)*uniform(14));
status=round(1+(2-1)*uniform(16));
cascon=round(1+(2-1)*uniform(17));
output;
end ;
drop i;
run;

/*formats */
proc format;
value gene 1= 'Gene1' 2= 'Gene2' 3= 'Gene3';
value cascon 1='Case' 2='Control';
value age 1='<18' 2="'18-35'" 3="'">35';
value ethnic 1='Asian' 2='Caucasian' 3='Other';
value status 1='Abnormal' 2='Normal ';

proc sort data=genestat ;
by gene;
format gene gene. cascon cascon. status status. age age. ethnic ethnic.;
run;

Let’s consider a model with variable status, age and ethnic are as predictors.

/*proc logistic for calculating adjusted odds ratio*/
ods trace on;
ods output CLoddsWald=gene_cancer(where=(Effect="status Abnormal vs Normal"));

proc logistic data=genestat;
class status/param=ref ref=last;/* reference parameter ref=last
i.e. ref='Normal'*/
model cascon=status age ethnic / clodds=both;/* clodds =gives WALD confidence Interval for odds ratio*/
by gene ;
run;

ods output close;
ods trace off;

The MODEL statement names the response variable and the explanatory effects, including covariates, main effects, interactions, and nested effects. The CLASS statement names the classification variables to be used in the analysis. The CLASS Statement permits specification of a reference level. By default, the lowest level of the variable placed in the CLASS Statement is treated as the reference category. The BY statement is used to obtain separate analyses on observations in groups defined by the BY variables.

The output table is obtained as

This shows that Gene1 and Gene2 are less likely to have the abnormal genotype status in case than control. Adjusted odds ratio for Gene3 shows that the odds of abnormal genotype occurring in the case group are higher than it occurring in control group.

Let's now consider the model where status is the only predictor.

/*proc logistic for calculating unadjusted odds ratio*/
ods trace on;
ods output CLoddsWald=gene_cancer(where=(Effect="status Abnormal vs Normal"));

proc logistic data=genestat;
class status/param=ref ref=last;/* reference parameter ref=last
i.e. ref='Normal'*/
model cascon=status / clodds=both;/* clodds =gives WALD confidence interval
for odds ratio*/
by gene ;
run;

ods output close;
ods trace off;

The output table is obtained as


This shows that the odds of abnormal genotype occurring in the case group are higher than it occurring in control group for gene 3 while it same for genes 1 and 2.

21.9.08

Odds ratio
Prepared by Prajitha Nair & Sreeja E V

In order to quantify the association between the exposure and the outcome of interest the incidence of disease in a group of individuals exposed to the supposed risk factor must be compared with the incidence in a group of persons not exposed. This comparison can be summarized by calculating either the ratio of the measures of disease occurrence for the two groups, which indicates the likelihood of developing the disease in the exposed individuals relative to those unexposed.In case-control studies, it is not possible to directly estimate disease incidence in those exposed and those unexposed, since people are selected on the basis of having or not having the condition of interest, not on the basis of their exposure status. It is however, possible to calculate the odds of exposure in the cases and in the controls.The odds ratio (OR) estimates the magnitude of association between the exposure and outcome. It is defined as the ratio of odds of an event occurring in one group to the odds of it occurring in another group, or to a sample-based estimate of that ratio. These groups might be an experimental group and control group.The 2x2 contingency table showing the relationship between the exposure and the disease is presented as follows:


Probability of being exposed among cases=a/(a+c)Probability of being non-exposed among cases=c/(a+c)Odds of being exposed among cases=a/cProbability of being exposed among controls=b/(b+d)Probability of being non-exposed among controls=d/(b+d)Odds of being exposed among controls=b/dOdds ratio = (odds of being exposed among cases)/ (odds of being exposed among controls)= (a/c)/ (b/d)= (a*d)/ (b*c)
In strict terms, the odds ratio obtained tells us how many more (or less, if the exposure is associated with a reduced risk) times likely the cases are to have been exposed to the factor under study compared with the controls.

If odds ratio is equal to 1 then this implies that the condition or event under study is equally likely in both groups. An odds ratio greater than 1 indicates that the condition or event is more likely in the first group. An odds ratio less than 1 indicate that the condition or event is less likely in the first group. The odds ratio can vary from zero to infinity.

Odds Ratio using SAS
Prepared by Prajitha Nair


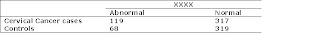
In the case-control study, the risk of cervical cancer was examined in relation to a gene XXXX. The status of the genes is abnormal and normal wherein normal is considered as the referent category.

Consider an example:data gene;input cat $7. genstatus $4. count;cards;case abn 119control abn 68case nor 317control nor 319;run;

ods output RelativeRisks=relrisk(where=(studytype="Case-Control (Odds Ratio)"));proc freq data=gene ;tables cat*genstatus/relrisk ;weight count;run;ods output close;

The table will be as follows:

Odds of exposure among cases=119/317Odds of exposure among controls=68/319Odds ratio= odds of exposure among cases/odds of exposure among controls =1.76

The odds ratio with respect to XXXX shows that the odds of abnormal genotype occurring in case group is 1.76 times higher than it occurring in control group. The 95% confidence interval for the odds ratio is obtained as (1.26, 2.46).The cervical cancer cases were 76% more likely to have abnormal genes than controls. In short, the odds ratio indicates that women who have abnormal genes were 76% more likely to develop cervical cancer than those with normal genes.